AI Search Doctor
Tells you why ChatGPT cites someone else for your question, and what to paste so it cites you.
Check you have these first
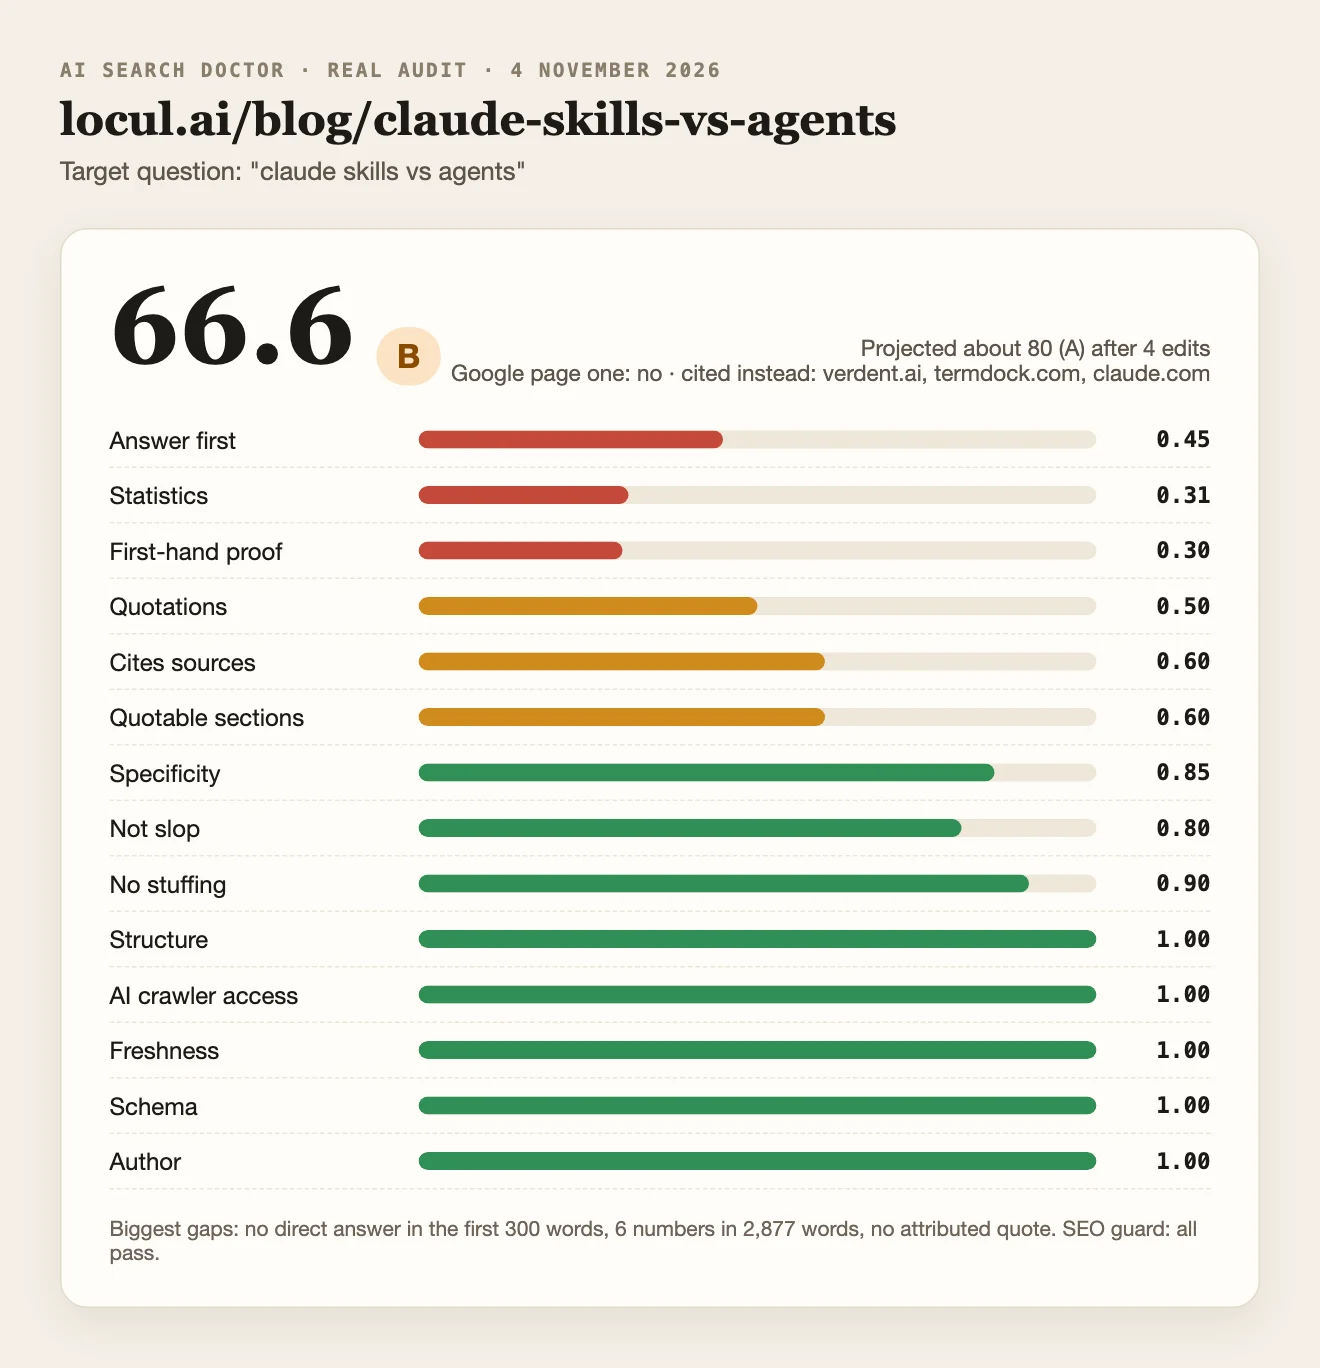
The score card from the real audit of a live locul.ai article on 4 November 2026, drawn from the bot's checker output.
1 / 1What AI Search Doctor does for you
Give it a page and the question people ask. It scores the page out of 100 on the things answer engines reward (a direct answer near the top, sourced numbers, real quotes, sections that make sense when quoted alone, crawler access), checks who gets cited for that question today, and hands you up to six edits in order of payoff, each with the exact text to paste and a note on what it does to your Google rankings. It never makes up a statistic: missing numbers come back as placeholders for you to fill. It changes nothing without your OK, and it re-checks the page four weeks after you publish.
- Scores a page out of 100 for being quoted by AI answer engines
- Checks who is cited for your question today and why
- Writes up to six ready-to-paste edits, in order of payoff
- Keeps every edit safe for your Google rankings
- Re-checks the page four weeks after you publish
What it hands you
AuditA real audit of a live blog post, run on 4 November 2026
Page: https://locul.ai/blog/claude-skills-vs-agents Question people ask: claude skills vs agents
AI search audit: Claude Skills vs Agents: How to Choose the Right One (https://locul.ai/blog/claude-skills-vs-agents)
Target question: claude skills vs agents | Score: 66.6 (B), projected about 80 (A) after edits 1 to 4
Cited today: Google AI Overview yes, this page not in it. Google page one: no. ChatGPT search: not cited.
Cited instead: AI Overview cites verdent.ai, levelup.gitconnected.com, termdock.com, go9x.com, danielmiessler.com, reddit.com, academy.claude.com. ChatGPT cites only claude.com and platform.claude.com.
Gap: the cited pages open with a two-line answer and a comparison table. This page opens with breadcrumbs, a summary block that ends in a product pitch, and two promo boxes.

Top edits, in order:
1. [answer_first 0.45] Where: directly under the H1, above both promo boxes (move them below Key takeaways).
   Paste: "Claude skills vs agents comes down to where the work runs. A skill is a SKILL.md instruction file that Claude loads into your current conversation when it recognises the job, so it changes how the work gets done. A subagent is a separate Claude with its own context window and tool list, so it changes where the work happens. MCP is neither: it connects Claude to outside systems."
   SEO: positive. The target words move into the first sentence and it is a featured-snippet sized answer.

2. [statistics 0.31] Where: "What a Claude skill actually is", after the progressive disclosure sentence.
   Paste: "Anthropic's docs put numbers on it: each installed skill costs about 100 tokens at startup (just its name and description), and the SKILL.md body, which loads only when the skill fires, should stay under 5,000 tokens. The name field is capped at 64 characters and the description at 1,024." Link: https://platform.claude.com/docs/en/agents-and-tools/agent-skills/overview
   SEO: neutral to positive.

3. [quotations 0.5, no attributed quote] Where: the same section, as a short blockquote.
   Paste: Anthropic's documentation: "Unlike prompts (conversation-level instructions for one-off tasks), Skills load on demand, so you don't have to repeat the same guidance across conversations." Link the same docs page.
   SEO: neutral.

4. [cites_sources 0.6, 3 external domains] Where: at each claim. Link the Agent Skills standard (agentskills.io) where it is named in the FAQ, Claude Code's subagents docs where the .claude/agents path is given, and modelcontextprotocol.io in "Where MCP fits". That takes the page to 5+ sources.
   SEO: neutral.

5. [passage_quotable 0.6] Two H2s open with throat-clearing. Replace the first sentence of each:
   "Where MCP fits": "MCP (Model Context Protocol) is an open protocol that connects Claude to outside systems such as an issue tracker or a database. It gives Claude reach, not judgement, so it is neither a skill nor a subagent."
   "What breaks six months in": "Skills and subagents both go stale for the same reason: they are static text. The procedure stays right while the facts it leans on, such as your pricing, your model choice or a removed feature, change underneath it."
   SEO: neutral.

6. [first_hand 0.3] Where: after "Two files you can copy".
   Paste: "[ADD: one dated test from your own setup, for example the same code review run once as a skill and once as a subagent, with how long each took and what came back]"
   SEO: positive. First-hand evidence is also what Google's helpful-content guidance rewards.

Off-page moves: the Reddit thread "Understanding Claude Skills vs. Subagents" on r/ClaudeAI is cited in the AI Overview. A genuinely useful answer there with the decision table is worth more than another on-page edit.
SEO guard: all pass now, and all six edits keep it passing (target words stay in title, H1, first 120 words and meta).
ScoreThe checker's raw score for the same page
The same page and question, after the bot judged the six reading criteria.
python3 geo_check.py https://locul.ai/blog/claude-skills-vs-agents --keyword "claude skills vs agents" --judged judged.json

AI search score 66.6/100 (grade B)
  [0.31] statistics        w11  only 6 stats in 2877 words; aim for 2+ per 300 words
  [0.45] answer_first      w12  add a 40-60 word answer capsule in the first 300 words
  [0.30] first_hand        w9   add your own test or result with numbers and a date
  [0.50] quotations        w9
  [0.60] cites_sources     w8   only 3 external domains; aim for 5+
  [0.60] passage_quotable  w6
  [0.85] specificity       w10
  [0.80] not_slop          w5
  [0.90] no_stuffing       w3
  [1.00] structure, crawl_access, freshness, schema, authorship, depth
  SEO guard: all pass
What it does each week
- Mondays at 09:00Re-scores every page on your list, flags any that slipped or got blocked to AI crawlers, and names the single best next edit.
- Daily at 09:30Re-checks pages whose edits went live four weeks ago and logs the before and after score.
Routines start switched off. Turn each one on when you are ready, and it asks before anything goes out.
A sample conversation
Why doesn't ChatGPT ever cite our pricing guide? tallyhq.example/blog/pricing-guide, people ask 'how much should a SaaS charge'.
Score 58 (C). The answer to the question first shows up in paragraph six, there are two numbers in 2,100 words and none have a source, and Perplexity cites two pages that open with a price table. First edit: a 50-word answer under the H1, ready to paste below. Five more after it.
Do the first two.
Snapshotted the old text, applied both, re-scored at 69 (B). I will check again on 2 December and tell you whether it is being cited.
Check it fits before you buy
- None required: it reads your public pages
- Optional: your CMS (such as WordPress) to apply approved edits
- The pages you want cited, and the question each one answers
- How edits get made: CMS, code repository or by hand
- Pages that are off limits, and your writing rules
First result: A full audit of your first page about 5 minutes after setup.
Plain files you can read and change
ai-search-doctor/
  bot.json
  files/config.json
  files/ledger.md
  files/playbook/edits.md
  files/playbook/judging.md
  files/tools/geo_check.py
  files/tools/rubric.json
  instructions.md
  jobs.json
  memory.md
Before you buy
Can I get a refund?
Yes. For 48 hours after you buy, press Refund on the bot in Locul or on your account page. The full amount goes back to your card and the bot is removed. No form, no questions.
Is this a subscription?
No. You pay once. It runs on the AI account you already have.
What do I need to run it?
Locul on your Mac or PC and Claude (through Claude Code on your computer). It also uses: None required: it reads your public pages; Optional: your CMS (such as WordPress) to apply approved edits.
Can I change how it works?
Yes. It is a folder of plain files. Ask it in plain English, or edit its instructions and playbooks yourself.